VLA model (vision-language-action)
A neural network that takes camera images and a text instruction and outputs robot actions.
Instead of programming each step, you tell the robot something like put the red cup in the sink, and the model decides how to move the joints. The same model can handle many tasks, which is why VLA models are at the center of current humanoid projects.
For a buyer this is still early. Demos often work in the setting where the model was trained and fail in a new kitchen. Ask for success rates on tasks in unfamiliar places, how long one action takes, and whether the model runs on the robot or needs a cloud connection.
Related terms
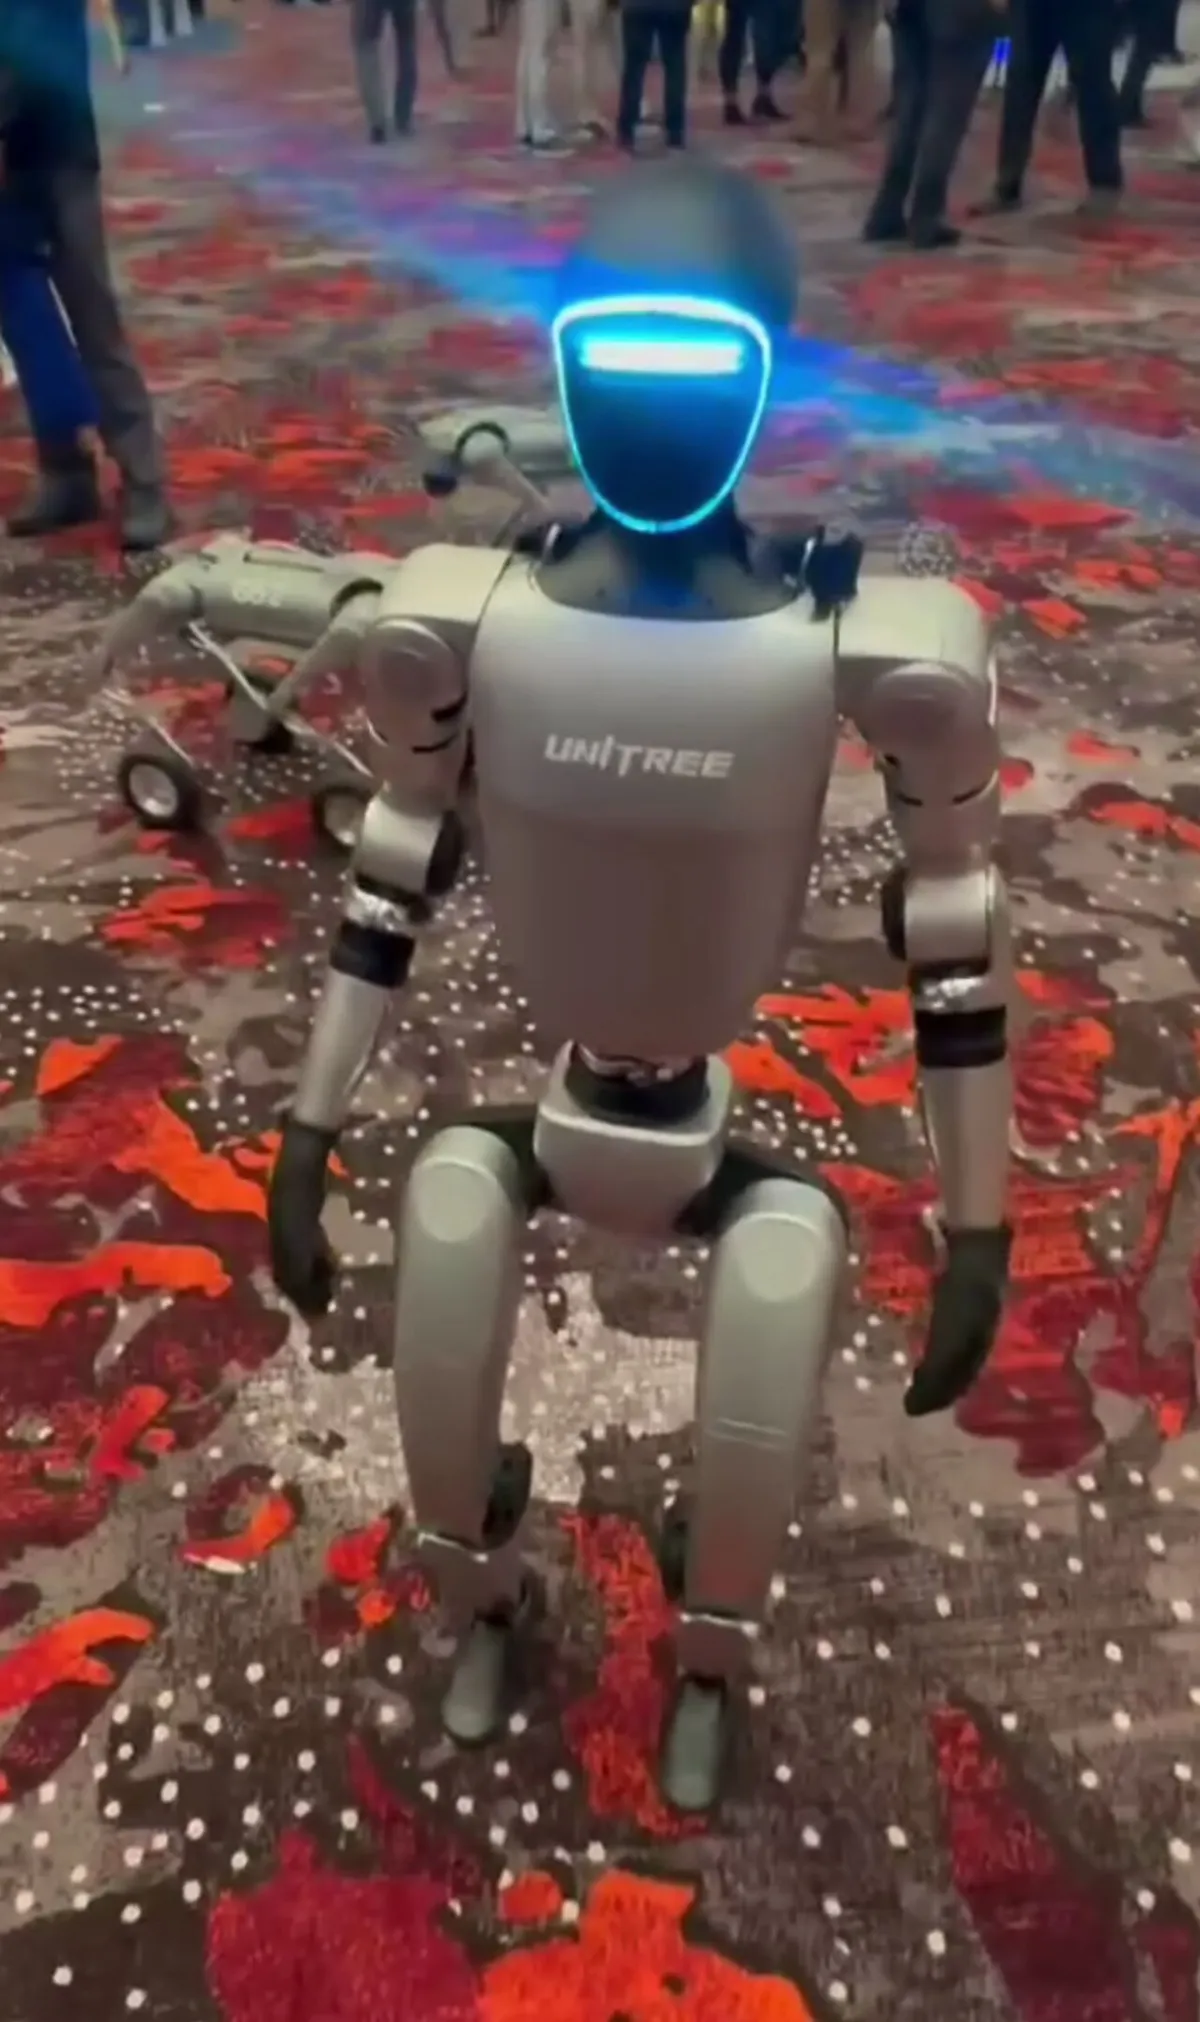 China
Humanoids & R&D
Unitree G1
Bipedal humanoid
Payload
2 kgRuntime
2 hSpeed
7.2 km/h$13,500 – $16,000price as of September 2026
On salePhoto coming soon
ChinaHumanoids & R&D
Unitree H1
Bipedal humanoid
Payload
7 kgRuntime
no dataSpeed
no data$90,000price as of September 2026
Made to orderPhoto coming soon
USAHumanoids & R&D
Figure 02
Bipedal humanoid
Payload
20 kgRuntime
5 hSpeed
3 km/hNot for sale, no price
Not for sale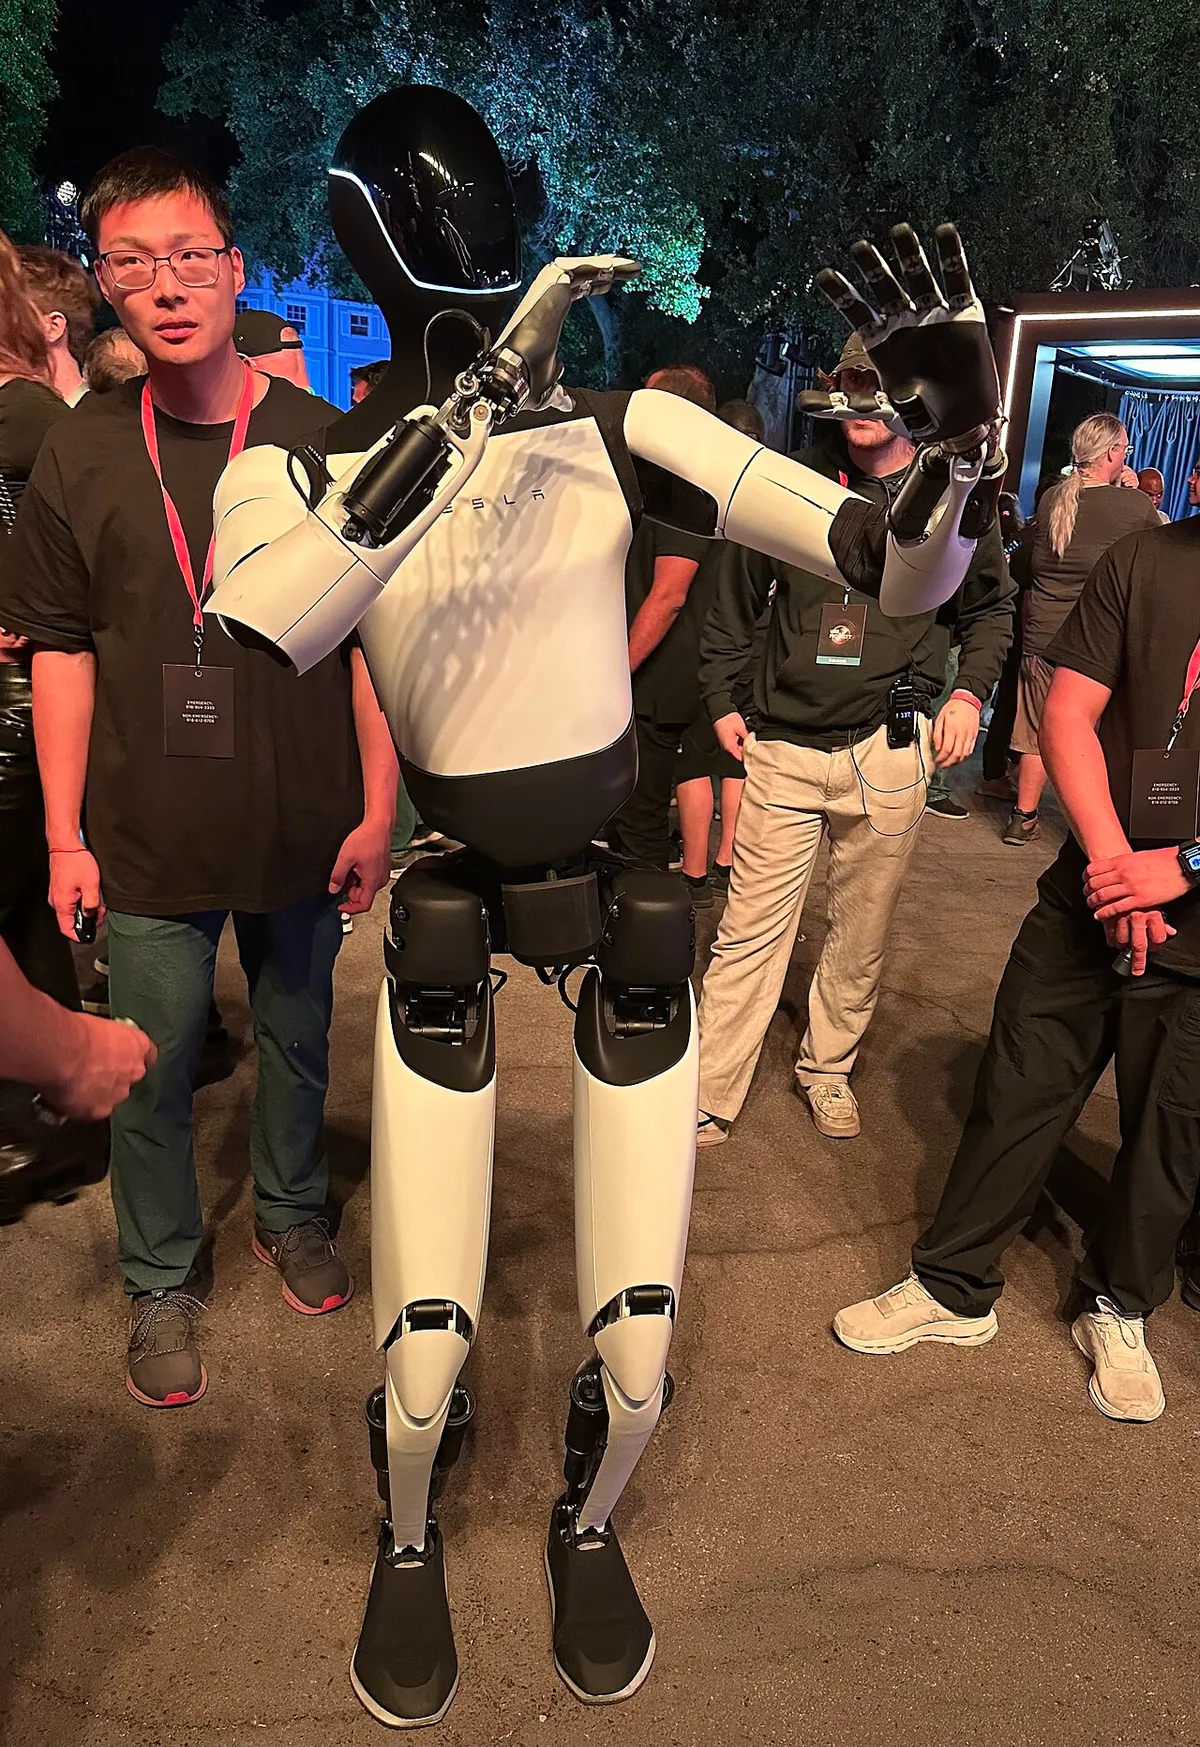 USA
Humanoids & R&D
Tesla Optimus
Bipedal humanoid
Payload
no dataRuntime
no dataSpeed
no dataNot for sale, no price
Not for sale