Reinforcement learning
Learning by trial and error, where good results are rewarded and bad ones are penalized.
The robot tries actions, gets a score and slowly finds what works. It is the main method behind stable walking and running of legged robots, because nobody can hand-code every muscle correction needed to keep balance on uneven ground.
It needs a huge number of attempts, so it is done in simulation first (see sim-to-real). For you as a buyer, it explains why a modern robot dog recovers after a push or a slip, and why behavior can improve through software updates.
Related terms
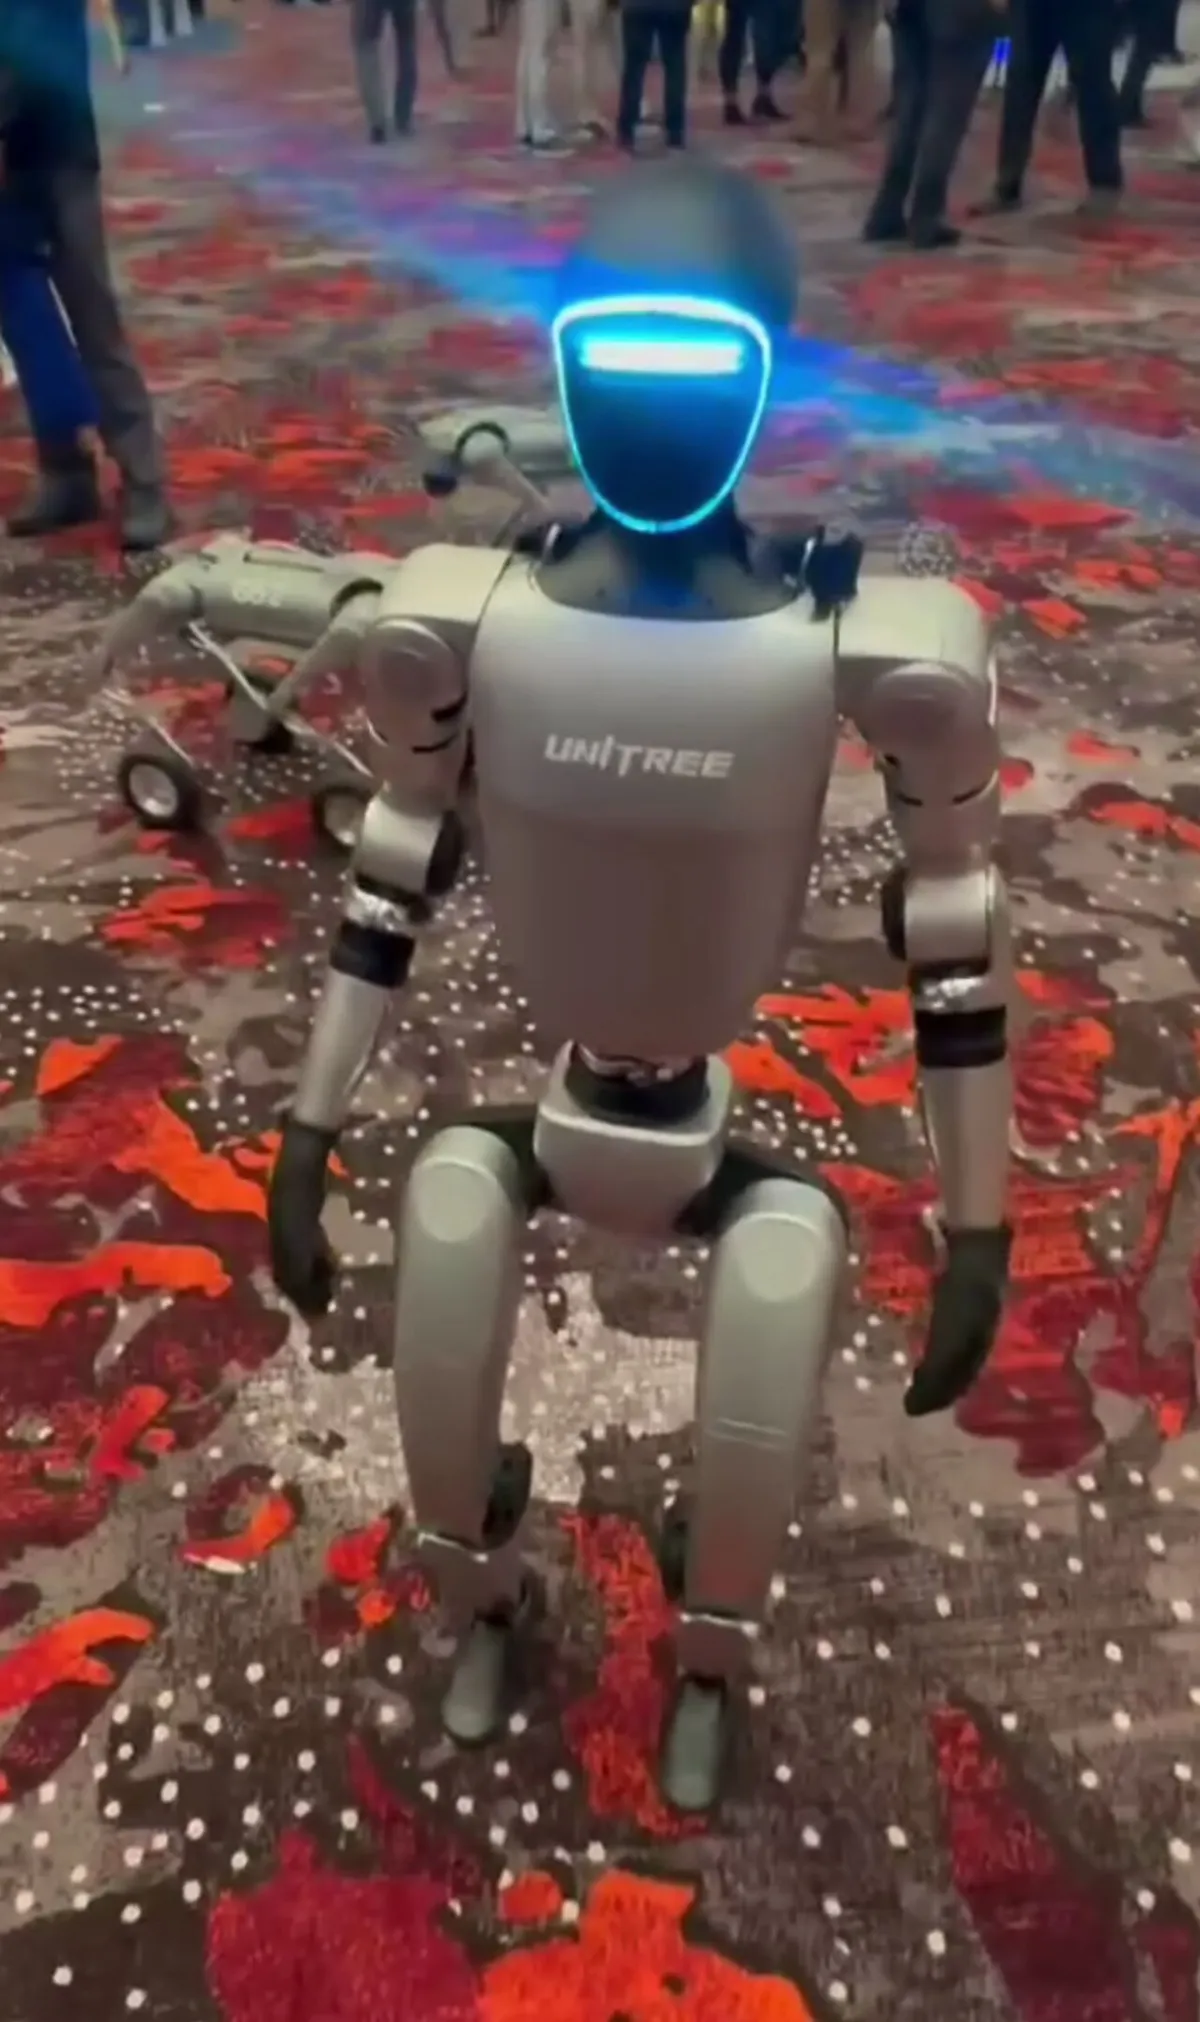 China
Humanoids & R&D
Unitree G1
Bipedal humanoid
Payload
2 kgRuntime
2 hSpeed
7.2 km/h$13,500 – $16,000price as of September 2026
On salePhoto coming soon
ChinaHumanoids & R&D
Unitree H1
Bipedal humanoid
Payload
7 kgRuntime
no dataSpeed
no data$90,000price as of September 2026
Made to orderPhoto coming soon
USAHumanoids & R&D
Figure 02
Bipedal humanoid
Payload
20 kgRuntime
5 hSpeed
3 km/hNot for sale, no price
Not for sale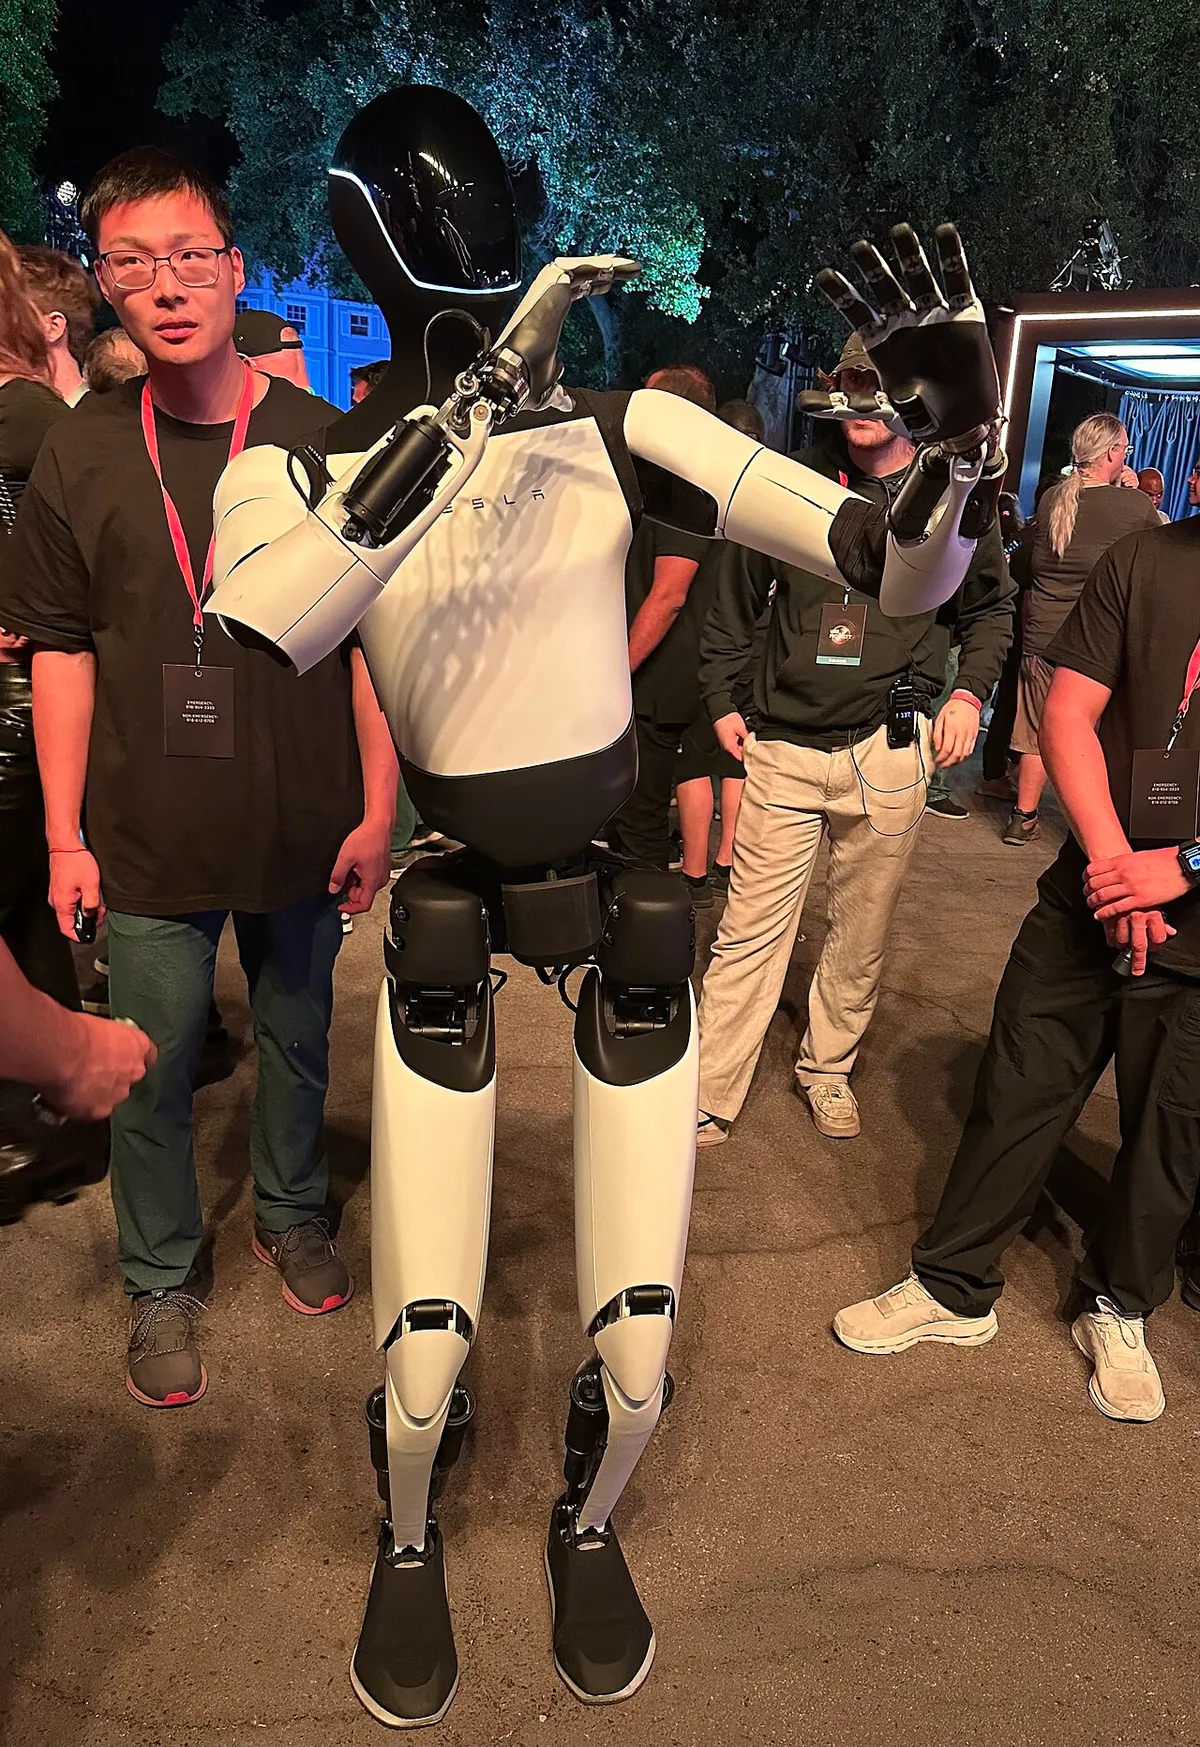 USA
Humanoids & R&D
Tesla Optimus
Bipedal humanoid
Payload
no dataRuntime
no dataSpeed
no dataNot for sale, no price
Not for sale